The distinction that does all the work
Most comparisons of this pair list attributes. Automation is rigid, agents are flexible, automation is fast, agents are smart. That framing invites you to pick a side. The useful version is narrower: who decides the sequence of steps, and when?
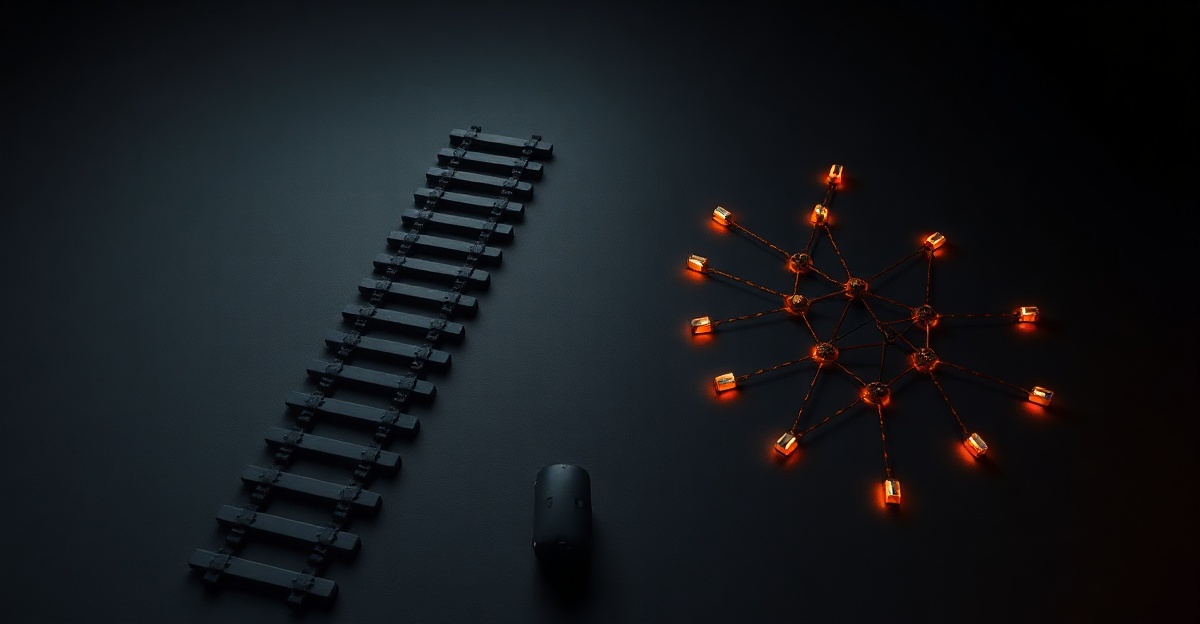
In automation, a human decided in advance and wrote it down. In an agentic system, the model decides during execution, from what it encounters. Everything people cite as a difference is downstream of that one fact. Cost, because a decided path runs the same way every time and a decided-at-runtime path pays for the deciding. Testability, because you can test enumerated branches and cannot test an open set. Supervision, because a script that breaks throws and an agent that misunderstands does not.
The test: can you enumerate the branches?
Sit down and try to list the cases. Not exhaustively, just try. What usually happens is one of two things.
You finish the list. Twelve cases, maybe thirty, a couple of awkward ones at the end. Then you do not need an agent, and using one is strictly worse: you have paid inference cost and given up repeatability to have a model rediscover, on every run, a set of branches you already know. A rules engine or a state machine does this cheaply and tells you when it hits something unhandled.
You cannot finish it, and not because you lack time, but because the input space genuinely is not enumerable. Inbound messages in free text. Documents from a hundred counterparties with no shared schema. That is where an agent starts earning its cost, because the alternative was a human doing it case by case.
The pattern most systems actually want
The framing is a false binary, and the most under-used option sits between them: one LLM call inside deterministic control flow.
The reason people reach for an agent is usually that the input is messy, not that the logic is open-ended. Messy input is a parsing problem. Put a single model call at the point of ambiguity, to normalise the input, classify the intent, extract the fields, and let ordinary code do the branching. You keep the language understanding, and you keep your tests, your repeatability and your cost model.
Most disappointing agent projects I have seen were this case implemented as a full agent. The task had language in it, language implied a model, and a model somehow implied handing over control flow. It does not.
What it costs, honestly
Per-run cost diverges as volume grows: a script's cost trends toward zero because the work was done once, while an agent pays the same tokens and the same seconds on every execution. At low volume that is invisible; at high volume it is the business case, running the wrong way.
But the cost that surprises people is supervision. I run 35 agents in production. The monitoring behind them is three layers deep (a passive heartbeat, a watchdog that owns recovery, and an active probe that round-trips a real request) and none of the layers is optional, because each catches something the others structurally cannot. That is a standing operational cost with no equivalent on the automation side, and no model release reduces it.
Two things worth reading if you want the formal framing rather than mine. NIST's AI Risk Management Framework (AI 100-1) puts trustworthiness on the organisation rather than the system, which is the governance shape of the same point. And Anthropic's Language Models (Mostly) Know What They Know gives the measured version of why supervision cannot be delegated to the model's own sense of certainty: calibration holds up on constrained choices and degrades on unfamiliar tasks, and an agent inferring its own next step is permanently in the second regime.
Choosing, in four lines
- Fixed path, fixed logic → a script or scheduled job.
- Fixed path, fuzzy content → one LLM call inside deterministic code.
- Branching path, enumerable branches → a rules engine or state machine.
- Open-ended decisions a human would otherwise make case by case → an agent, with supervision budgeted from day one.
If none of those fit cleanly, the question is usually not which tool but whether the process is understood well enough to automate at all. For the fuller version of that argument, see when not to use AI agents, or back up to the agentic AI pillar.
Frequently asked questions
What is the difference between AI agents and automation?
Automation executes a path a human decided in advance. Same input, same steps, same output. An AI agent decides the path at runtime, choosing which tools to call and in what order based on what it encounters. Everything else follows from that: automation is cheap, testable and repeatable; an agent buys you the ability to handle inputs nobody enumerated and charges you variance, latency and supervision in exchange.
When should I use automation instead of an AI agent?
Whenever you can enumerate the branches. If the decision points are listable, a rules engine or state machine handles them at a fraction of the cost, with tests that actually pass or fail. Also whenever the same input must always produce the same output, whenever per-item margin is thin and volume is high, and whenever a silent wrong answer is expensive — agents fail without erroring, which automation does not.
Can you combine AI agents and automation?
That is usually the right answer and it is the most under-used pattern. Put a single LLM call where the language ambiguity is — parsing a messy email, classifying an intent, extracting fields — and keep the control flow in deterministic code. You get the language understanding without handing over the branching, which means you keep your tests, your repeatability and your cost model.
Are AI agents more expensive than automation?
Per run, almost always, and the gap widens with volume. A script amortises to near zero because the work was done once when it was written; an agent pays the same inference cost and latency on every execution. The larger cost is the one nobody budgets: supervision. Agents fail without throwing, so somebody has to notice, which is an ongoing operational cost that model improvements do not reduce.
Is RPA the same as automation in this comparison?
RPA is one implementation of it. The distinction on this page is about who decides the path, not which tool executes it — an RPA bot, a cron job, a state machine and a shell script all sit on the automation side because a human decided the sequence in advance. The question is not which technology you own, it is whether the branching is knowable before runtime.